The Genome We Can Read but Cannot Yet Fully Understand
The human genome contains over three billion DNA bases, but reading the genetic code is only the beginning of understanding human biology. Only a small fraction of the genome consists of protein-coding regions, while the non-coding landscape contains regulatory elements, non-coding RNAs, and other regions whose functions are still being uncovered. Even among the roughly 20,000 human protein-coding genes, many remain poorly characterized or incompletely annotated.
Next-generation sequencing (NGS) technologies can now generate enormous amounts of genomic information rapidly, yet translating these vast lists of DNA variants into meaningful biological knowledge remains a major challenge.
This functional annotation gap becomes particularly important in translational medicine. When an NGS pipeline identifies a rare genetic variant, identifying the alteration is only the first step; the more difficult question is determining what that change actually does. A genetic alteration may affect gene regulation, protein structure or function, molecular interactions, or biological pathways. Connecting these molecular changes to disease mechanisms is essential if medicine is to move beyond simply reading genomes toward truly understanding them.
What Does an Unknown Gene Do?
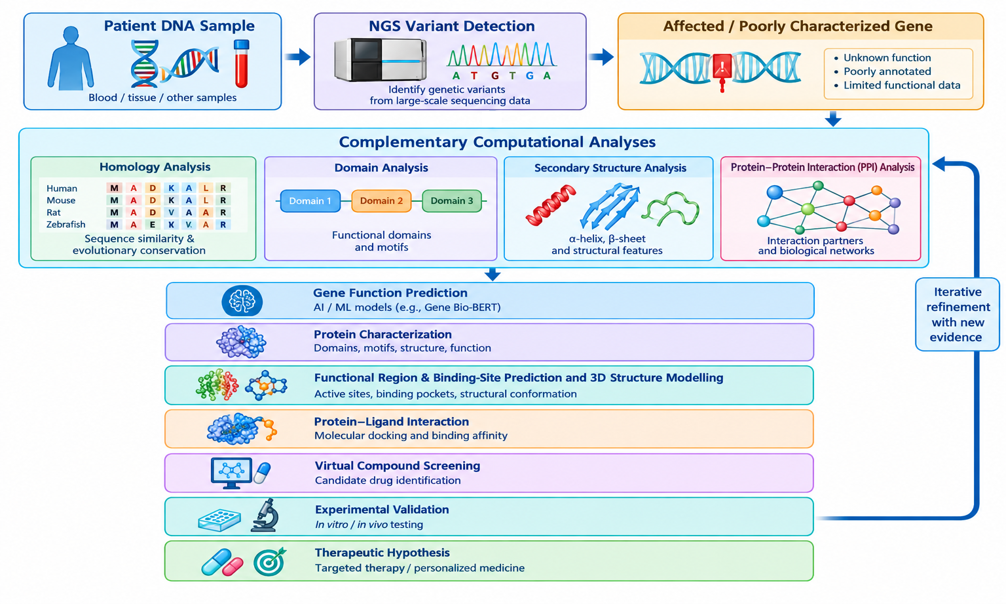
Traditional gene-function annotation relies on several complementary approaches, including sequence similarity, evolutionary conservation, protein-domain analysis, protein–protein interactions, and curated biological databases. While these methods remain foundational, the increasing scale and diversity of biomedical data create an opportunity for artificial intelligence to learn relationships across multiple biological dimensions.
Our early work focused on protein function using domain analysis and protein–protein interaction information. One example was Butyrylcholinesterase (BChE), where we investigated conserved domains and interaction partners to generate computational hypotheses about its biological functions. This work showed how computational analysis can provide clues about poorly understood biological roles.
This experience established an important principle that continues to guide our research. Biological function is rarely determined by one piece of information alone.The same principle became increasingly important when our research moved from individual proteins to disease-associated networks. In Alzheimer’s disease, we used computational approaches to investigate protein interaction networks and relationships among disease-associated proteins.
This network-centric perspective provided a foundation for the next stage of our work, which connects biological understanding with therapeutic discovery. We subsequently explored computational approaches for protein–compound prediction and candidate drug identification. However, these investigations highlighted a fundamental challenge: how can we confidently investigate a potential therapeutic target when the biological function of the underlying gene is itself poorly understood? This precise question led us toward the use of deep representation learning for gene-function prediction.
AI for Predicting Gene Function
To address this challenge, we developed Gene Bio-BERT, a deep learning framework for predicting the functionality of poorly annotated human genes. The framework uses human gene information, transformer-based contextual representations, and feature integration to generate functional predictions for poorly characterized genes.
In our study, Gene Bio-BERT achieved 94.5% accuracy and an F1 score of 0.87, demonstrating the potential of deep representation learning for gene-function prediction. An evaluation involving an unannotated gene also produced a similarity score of 0.84, illustrating how such models can generate candidate functional descriptions for genes with limited annotation.
The significance extends beyond prediction itself. An AI-generated biological hypothesis can be investigated using gene-expression data, protein-interaction networks, structural modelling, and laboratory experiments. In this sense, AI should not replace biological research; rather, it should help scientists determine which biological questions are most valuable to test experimentally.
From Genes to Disease Mechanisms
Understanding the baseline function of a gene provides an important foundation for investigating how genetic variation contributes to disease. Diseases such as breast cancer, Alzheimer’s disease, and Parkinson’s disease involve complex interactions among genes, proteins, and biological pathways. Similarly, congenital conditions, including structural heart defects, can involve genomic variants whose biological consequences are difficult to interpret from sequence information alone.
A variant may affect a gene, alter the function or regulation of its encoded product, influence interactions with other proteins, and ultimately disturb a biological pathway. Computational network analysis can help investigate these relationships at a systems level.
Emerging AI technologies are expanding these capabilities. Protein language models can learn representations from protein sequences, while Graph Neural Networks (GNNs) can model biological systems as networks of proteins and their relationships. Combining sequence-based and network information could provide richer models of protein function. However, these computational predictions require biological and experimental validation before they can be considered established mechanisms.
New Technologies Driving the Next Breakthrough
The next major advance in functional genomics is likely to come from integrating different types of biological information. Future multimodal AI systems could combine genomic variants with biomedical literature, gene-function information, protein sequences, structural information, interaction networks, and disease phenotypes.
Explainable AI will also become increasingly important. In biomedical applications, a prediction alone is rarely sufficient; researchers need to understand the evidence supporting a prediction, its uncertainty, and the biological relationships that influenced the model. The objective should therefore be to develop AI systems whose predictions are interpretable, reproducible, and experimentally testable.
Where Do We Go From Here?
Over the next five to ten years, I anticipate increasing convergence between genomics, artificial intelligence, structural biology, and systems biology. Future systems may place genetic variants within a broader context of affected genes, predicted functions, protein structures, interaction partners, pathways, and disease phenotypes.
Such integration could be particularly valuable for complex diseases where individual genetic variants remain difficult to interpret in isolation. For Breast cancer, Alzheimer’s disease, Covid-19 and Parkinson’s disease, combining genomic information with AI-based functional prediction and biological networks may help researchers investigate how genetic changes influence molecular and cellular processes. Similar approaches may help investigate variants associated with developmental disorders.
AI-generated predictions, however, should remain hypotheses until supported by appropriate biological evidence and experimental validation. The most valuable biomedical AI will not necessarily be the system that simply produces the highest prediction score. It will be the system that generates biologically meaningful, interpretable, and experimentally testable hypotheses.
The journey from an unknown gene to personalized medicine is therefore not a single technological step, but a chain of discoveriesfrom identifying a genetic change, to understanding its functional consequences, to connecting those consequences with disease biology, and eventually to developing evidence-based therapeutic strategies. Artificial intelligence can become an important bridge between genomic information and biological knowledge, helping transform unknown genes into testable hypotheses and genomic information into new possibilities for personalized medicine.